Last Updated: November 13, 2026
Quick Summary
Reducing unplanned maintenance callouts comes down to seven strategies: criticality-based preventive schedules, a first-time fix target, a work order checklist, scheduling software, a fixed callout triage workflow, root-cause analysis after every event, and monthly callout metrics. Together these cut repeat visits and after-hours emergencies.
- Score each asset on safety impact, downtime cost and repair lead time to set inspection frequency.
- Dispatching without the needed part is the most common cause of a repeat callout.
- Use three severity tiers and score safety first, then downtime cost, then customer impact.
- Ask why five times after every unplanned event and assign one corrective action with an owner and date.
- Track callout frequency, repeat-callout rate, response time, first-time fix rate and total cost per incident monthly.
Table of Contents
- What Unplanned Maintenance Callouts Actually Cost Your Business
- Preventive Maintenance Best Practices That Cut Emergency Callouts
- First-Time Fix Rate Improvement: The Metric That Kills Repeat Callouts
- The Maintenance Work Order Checklist Every Technician Should Carry
- How Maintenance Scheduling Software Prevents After-Hours Emergencies
- A Step-by-Step Callout Triage and Dispatch Workflow
- Step 1: Capture the details before you promise anything
- Step 2: Score severity against fixed tiers
- Step 3: Verify the fault before dispatch
- Step 4: Match the technician to the fault, not just the postcode
- Step 5: Confirm parts and tools before the van leaves
- Step 6: Dispatch with a brief, not just an address
- Step 7: Set a check-in and log the outcome
- Escalation rules that stop small jobs becoming emergencies
- Root-Cause Analysis After Every Unplanned Event
- Request a Demo and Put Your Callout Plan Into Action
- Frequently Asked Questions
What Unplanned Maintenance Callouts Actually Cost Your Business
Unplanned maintenance is any repair work that happens without warning and without a place on the schedule.
The costs stack up in ways that don’t show on a single invoice:
- After-hours labor premiums and callout fees
- Idle time while a technician waits for parts or access
- Jobs bumped off the schedule, which pushes other work late
The Canadian Centre for Occupational Health and Safety notes that planned maintenance also protects worker safety, not just uptime.
The real damage is cumulative. One emergency callout rarely sinks a week. Ten a month will.
Preventive Maintenance Best Practices That Cut Emergency Callouts
Preventive maintenance is scheduled work done on equipment before it fails. Done well, it is one of the most effective ways to reduce unplanned maintenance callouts. Done badly, it wastes technician hours and creates new problems.
The best practices that actually work:
- Set service intervals from the manufacturer’s guidance and your own failure history
- Group tasks by location so one visit covers several assets
- Track completion rates, not just scheduled dates
Build a Schedule Around Asset Criticality
Not every asset deserves the same attention. Asset criticality is a ranking of equipment by how much damage its failure causes.
Score each asset on three factors: safety impact, downtime cost, and repair lead time. High scorers get frequent inspections and a stocked spare. Low scorers get basic annual checks.
Technicians who plan around critical assets need a schedule that flexes with demand. How to create efficient technician schedules walks through building one that holds up.
Balance Preventive Work Against Over-Maintenance
Here’s what most guides miss: too much preventive work is its own failure mode. Teams that service everything on a fixed calendar burn hours on healthy equipment and skip the assets that actually need attention.
The fix is to let condition guide frequency. If an asset passes three inspections with no issues, stretch the interval. If it fails twice, shorten it. Track the result either way.
First-Time Fix Rate Improvement: The Metric That Kills Repeat Callouts
First-time fix rate is the share of callouts resolved on the first visit without a return trip. It is the clearest signal of whether your callout process is working.
Three things drive it up:
- Diagnostic skill. Technicians who find the root cause, not just the symptom, fix it once.
- Parts on the truck. A van stocked for common failures cuts return visits sharply.
- Clear job notes. The next technician needs to know what was done and what was left.
A common mistake is treating a repeat callout as bad luck. It’s a process gap, and the fix is systematic. How to reduce field rework in HVAC lays out a seven-step approach to closing those gaps.
The Maintenance Work Order Checklist Every Technician Should Carry
A maintenance work order is the record of a single job: what was requested, what was found, what was done, and what parts were used. A tight checklist on every work order prevents the gaps that cause repeat visits.
- Asset ID and location confirmed
- Reported fault and actual fault noted separately
- Root cause identified, not just the symptom
That last item matters more than most teams realize. Signed work orders speed up billing and settle disputes later.
How Maintenance Scheduling Software Prevents After-Hours Emergencies
Maintenance scheduling software can keep preventive tasks visible and assigned, which helps reduce missed inspections.
YourRadar offers dispatch mapping and automated timesheets in one mobile platform, which supports field-to-office communication.
Scheduling is only half of it. The other half is what happens when a callout lands anyway.
A Step-by-Step Callout Triage and Dispatch Workflow
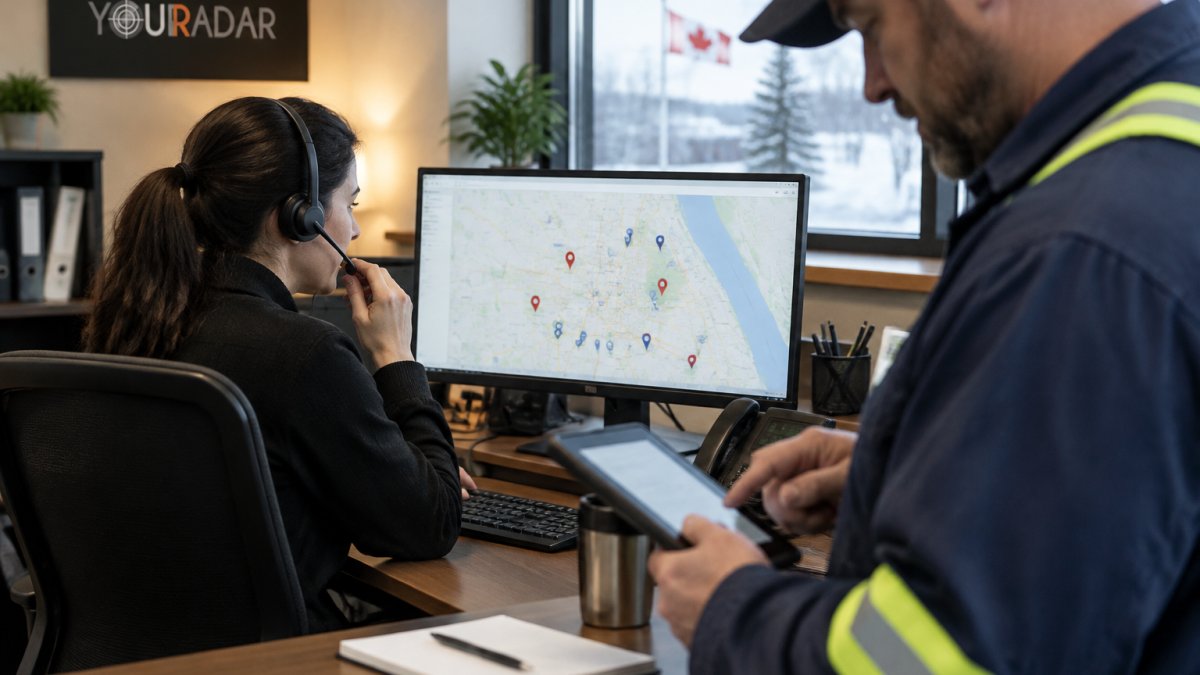
A callout triage workflow is a fixed sequence for handling emergency requests, so dispatchers decide fast and consistently instead of improvising under pressure. The goal is not to answer faster. It is to send the right technician with the right information and the right parts on the first trip. Here is the workflow we recommend, with the decision rules that make each step repeatable.
Step 1: Capture the details before you promise anything
Get the asset ID, the exact symptom, the site contact, access instructions, and whether the site is occupied. Ask the caller what changed: a new noise, a leak, a tripped breaker, a temperature drift.
Watch out: promising a response time before step 2 locks you into a priority that the evidence may not support.
Step 2: Score severity against fixed tiers
Use three tiers so every dispatcher applies the same logic:
- Tier 1, safety or regulatory risk. Fire, gas, electrical hazard, loss of heating in freezing conditions, or anything that puts occupants at risk. Dispatch immediately and escalate to a supervisor.
- Tier 2, critical asset down. Production, revenue, or a service obligation is affected, but there is no immediate safety risk. Dispatch within the current shift and confirm parts availability first.
- Tier 3, degraded but stable. The asset is running below spec or a non-critical unit is down. Schedule it into the next available slot rather than paying after-hours premiums.
Score safety first, then downtime cost, then customer impact. A Tier 3 call at 9 p.m. is usually a next-morning job, and saying so protects both the schedule and the labor budget.
Step 3: Verify the fault before dispatch
A short phone or video check with the site contact prevents a large share of unnecessary trips. Ask for a photo of the nameplate, the fault code on the controller, or a short video of the symptom. Many modern controllers display a fault code, and a photo of that code can help a technician prepare for the visit.
Step 4: Match the technician to the fault, not just the postcode
Check three things: skill match, proximity, and current workload. The nearest technician is the right choice only when they have the skill for that asset class. Otherwise you trade travel time for a second visit.
Step 5: Confirm parts and tools before the van leaves
Check the likely fix against van stock and the parts crib. If the part is not on the truck, either stage it for pickup on the way or reschedule to a time when it is available. Dispatching without the part is the most common cause of a repeat callout.
Step 6: Dispatch with a brief, not just an address
Send the fault description, the asset history, the last service date, site access notes, and any safety requirements. A technician who arrives already knowing the asset’s failure pattern diagnoses faster.
Step 7: Set a check-in and log the outcome
A short call or message at arrival confirms the diagnosis and lets the dispatcher adjust if the job is bigger than expected. Close the work order with the actual fault, root cause, parts used, and time on site.
Escalation rules that stop small jobs becoming emergencies
Set written triggers for escalation: a Tier 1 callout, a second visit to the same asset within a set window, or a job that runs past its estimated time.
For a deeper look at handling urgent requests, see how to handle urgent callouts efficiently. And if response times are the real problem, how to improve field technician response times covers the practical fixes.
Here is the triage workflow we recommend, with the decision rules that make each step repeatable.
| Step | What to do | Key rule |
|---|---|---|
| 1 | Capture asset ID, symptom, site contact, access | Don’t promise a response time yet |
| 2 | Score severity against fixed tiers | Safety first, then downtime cost, then customer impact |
| 3 | Verify the fault before dispatch | Ask for photo of nameplate or fault code |
| 4 | Match technician to the fault | Check skill match, proximity, current workload |
| 5 | Confirm parts and tools before the van leaves | Dispatching without the part causes repeat callouts |
| 6 | Dispatch with a brief, not just an address | Send fault description, asset history, access notes |
| 7 | Set a check-in and log the outcome | Close with actual fault, root cause, parts, time |
Root-Cause Analysis After Every Unplanned Event
Root-cause analysis is the practice of asking why an asset failed until you reach the real cause, not the surface symptom. Run it after every unplanned event, even small ones, because the small ones are where patterns hide. The point is not the report. The point is the corrective action that stops the same callout from returning.
A repeatable method for trades teams
A full formal analysis is overkill for most callouts. Use a short version that fits on one page of the work order:
- Describe the event. What failed, when, on which asset, and who attended.
- Ask why five times. Why did the pump stop? The bearing seized. Why did it seize? Lubrication was missed. Why was it missed? The task was on the schedule but not assigned. Why? The planner left and nobody took over the queue. Why? No handover process. The fifth answer is the one you can fix.
- Classify the cause. Was it mechanical, human, environmental, or a process gap? Most repeat callouts trace to a process gap rather than a worn part.
- Assign one corrective action with an owner and a date. A finding without an owner is a note, not a fix.
- Record it against the asset. The failure history is what makes future schedules smarter.
Turn callout records into callout metrics
A callout log is only useful if you measure it. Track these five numbers monthly, by asset and by site:
- Callout frequency: callouts per asset per month. Rising frequency on one asset is an early warning.
- Repeat-callout rate: the share of callouts that are a second visit to the same asset within a set window, such as 30 days. This is the single best indicator of whether first-time fixes are holding.
- Response time: from call logged to technician on site. Split it into dispatch time and travel time so you know which to fix.
A common pattern is that a small number of assets generate a large share of callouts. Ranking assets by callout frequency and total cost per incident tells you where to start.
Close the loop with corrective actions
If the answer is a missed inspection, fix the schedule and the assignment. If it is a parts gap, adjust van stock.
Watch out: closing a work order without a corrective action is how the same fault returns next quarter under a different technician’s name.
Teams that skip this step see the same failures return.
Request a Demo and Put Your Callout Plan Into Action
Fewer emergency callouts come from a system, not luck. Criticality-based schedules, a first-time fix target, a work order checklist, and root-cause follow-up all compound over time.
YourRadar offers dispatch mapping, automated timesheets, and customer portals for trades teams, backed by KDI’s more than 25 years of experience, with a simple interface for non-tech-savvy staff.
Request a demo to see how YourRadar fits your team.
If your callout log keeps growing, the fix starts with visibility.
Frequently Asked Questions
What causes unplanned maintenance callouts?
Most emergency callouts trace back to four causes: components worn past their service life, missed or skipped preventive tasks, operator error or misuse, and parts that fail without warning because no condition monitoring is in place. Poor documentation makes it worse, since technicians arrive without failure history and repeat the same diagnosis. Tracking the cause of each callout in your work orders shows which of these dominates in your business, and that tells you where to spend first.
How can businesses reduce emergency maintenance callouts?
Start by ranking assets by criticality so the equipment that halts revenue gets inspected first. Move those assets onto a fixed preventive schedule, stock the spare parts that fail most often, and give technicians a work order checklist so jobs close correctly the first time. Then measure callout volume, after-hours share, and first-time fix rate monthly. Maintenance scheduling software ties these together by flagging overdue tasks before they become breakdowns.
What is the difference between planned and unplanned maintenance?
Planned maintenance is scheduled in advance with known labor, parts, and timing, whether preventive, predictive, or corrective work booked off the back of an inspection. Unplanned maintenance is a breakdown or emergency callout that interrupts the schedule, pulls a technician off another job, and usually costs more in overtime and lost billable hours. Shifting the ratio toward planned work is the core goal of any callout reduction strategy.
How can maintenance software help prevent repeat callouts?
Software prevents repeats by keeping failure history attached to each asset, so the next technician sees what was replaced and when. It can auto-generate recurring work orders, flag overdue inspections, and route the nearest qualified tech through dispatch mapping, which shortens response time. YourRadar offers automated timesheets and a customer portal. Request a demo to see how the workflow fits a team your size.